# Layer Extraction (Qwen-Image-2.1 LoRA)
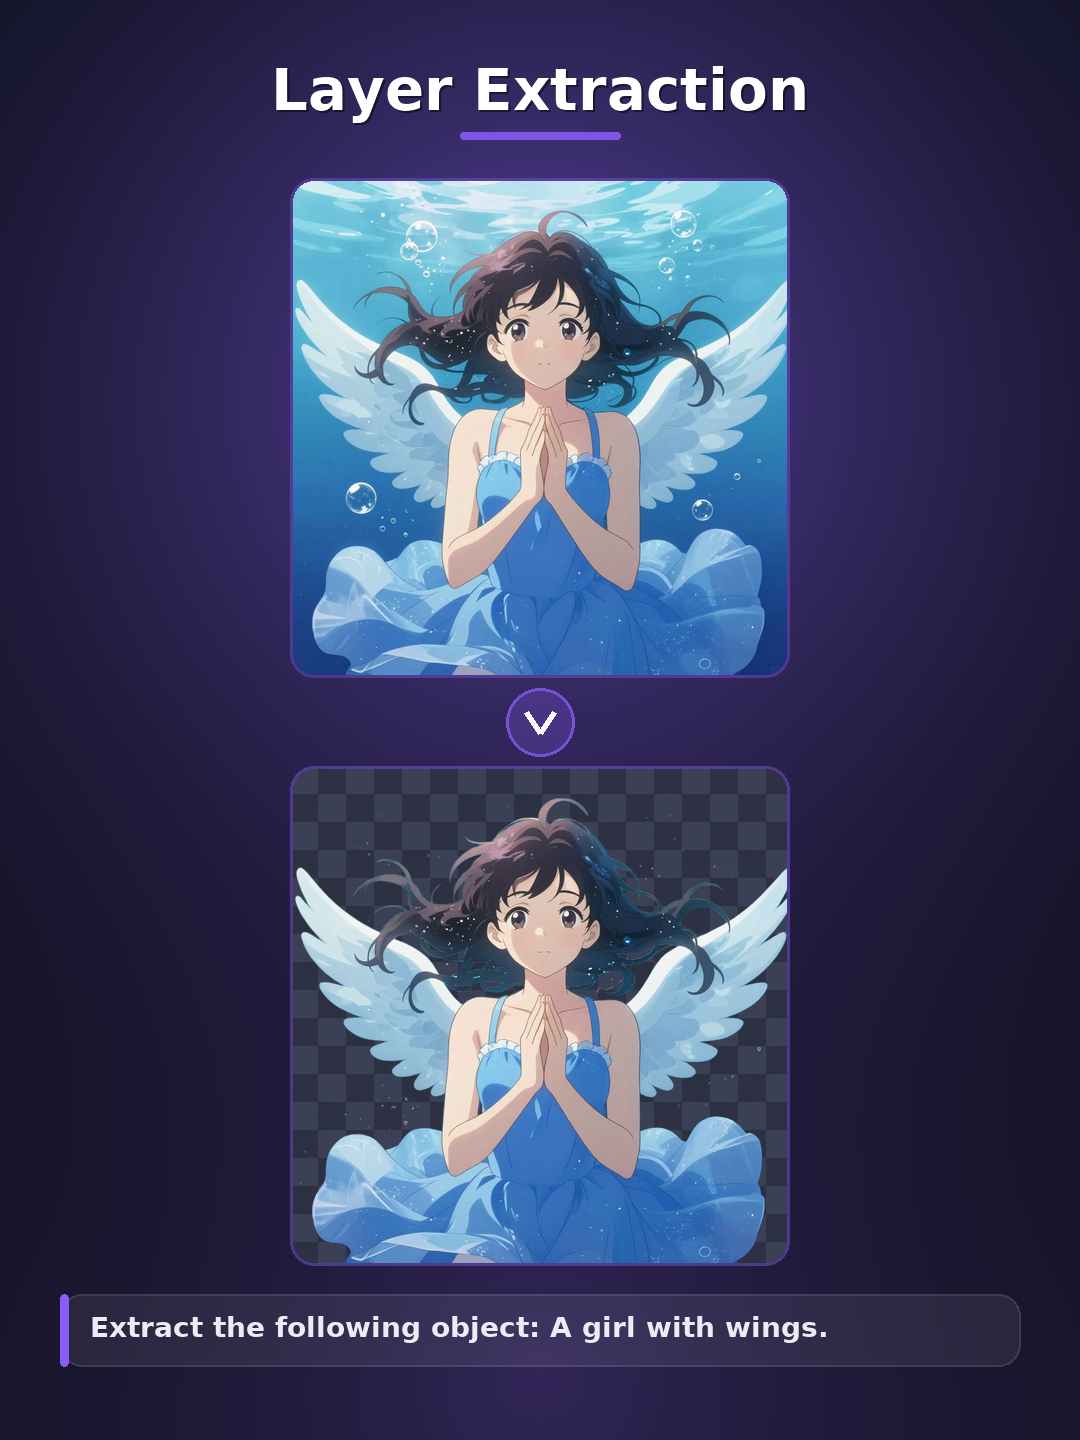
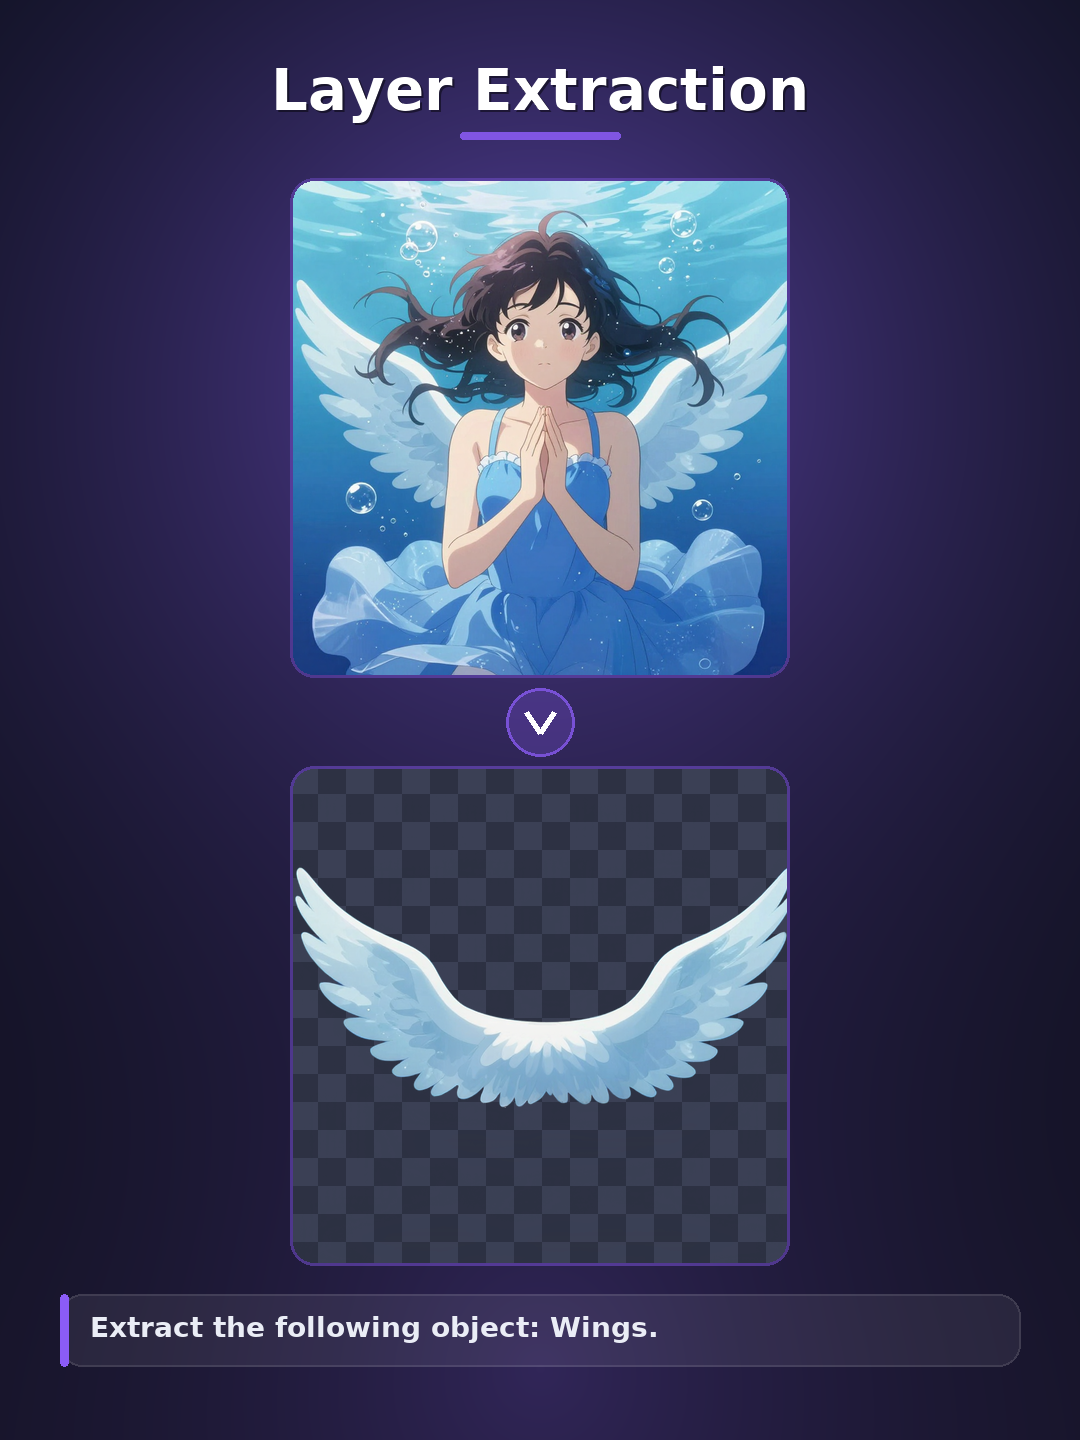
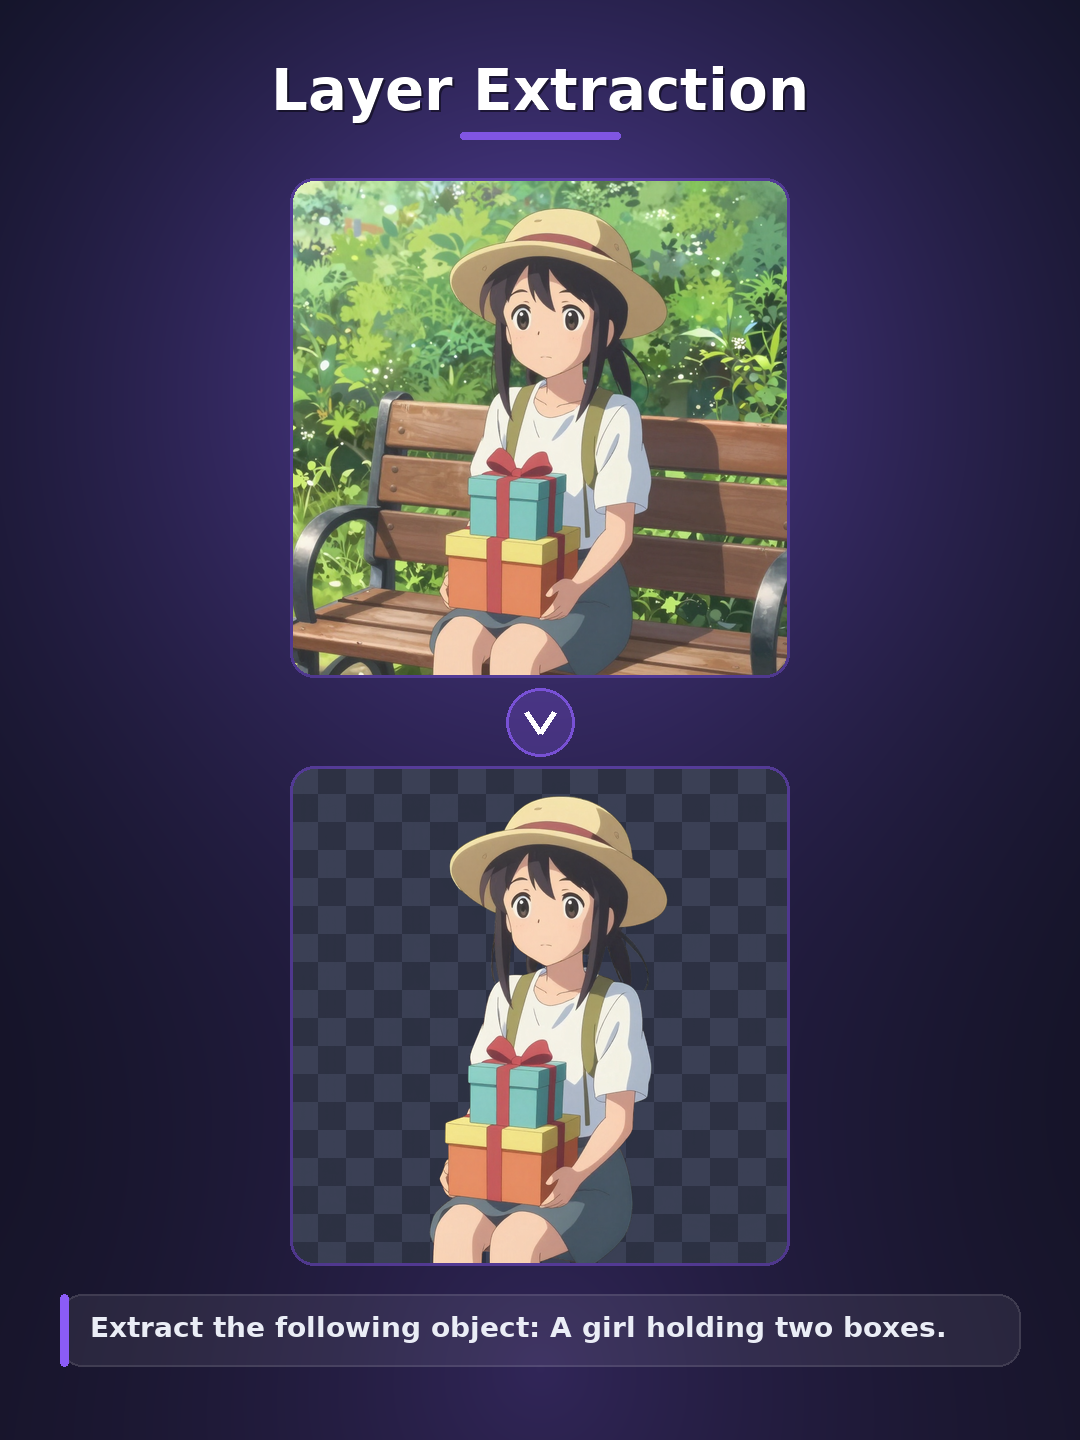
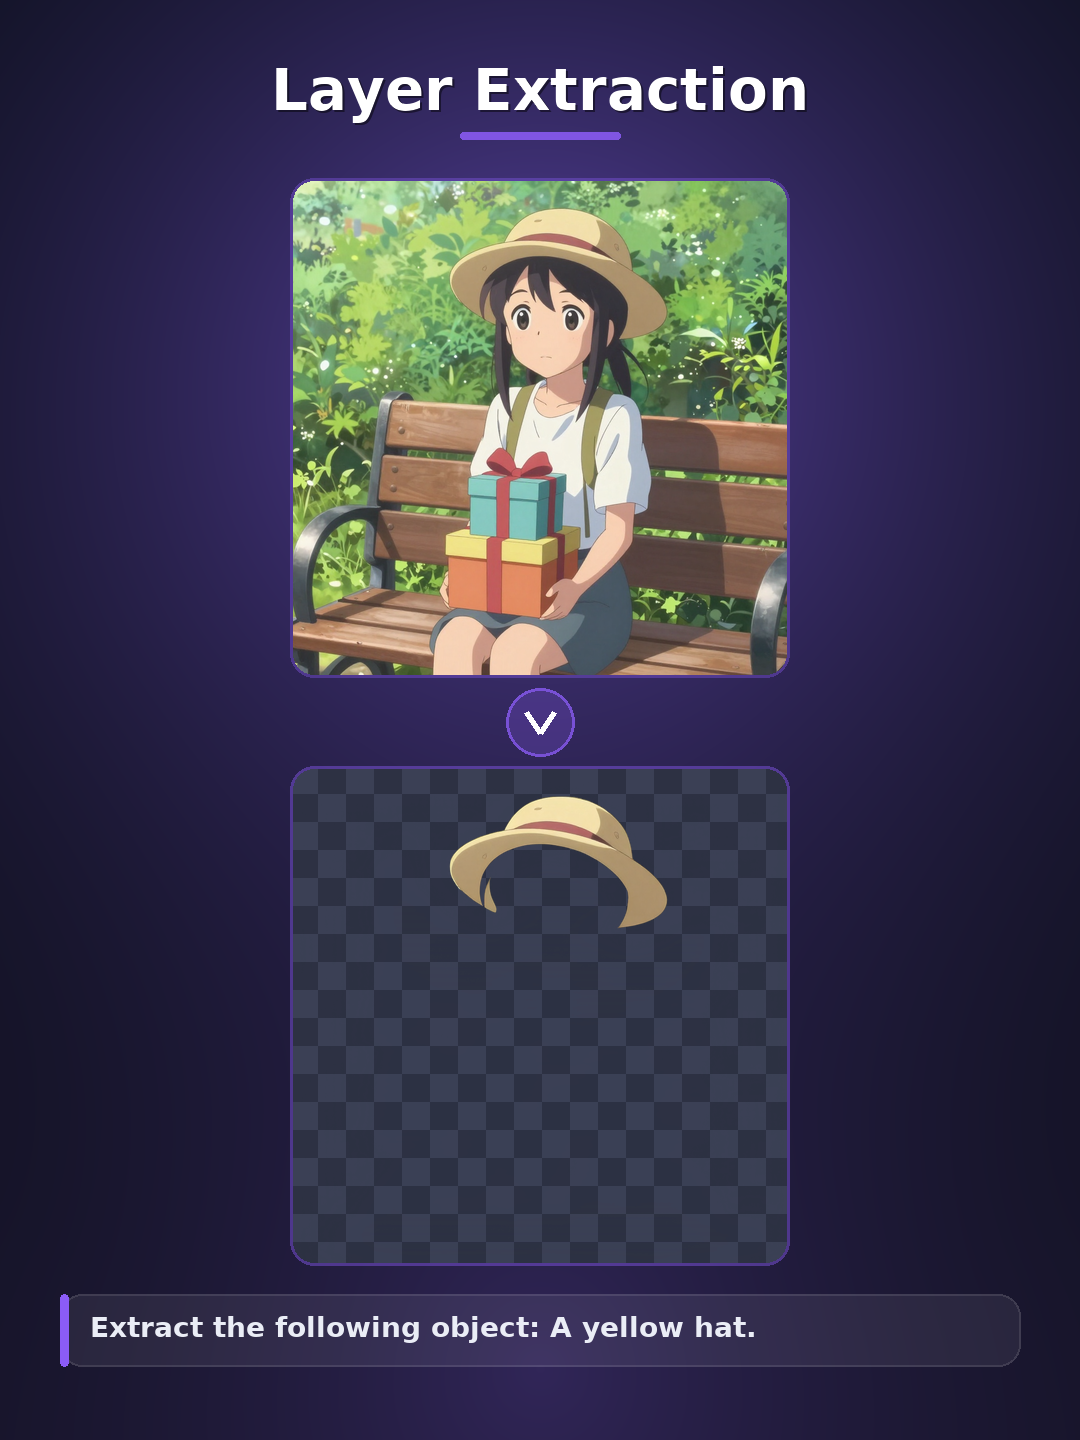
This model is designed to extract specific elements from an image. The extracted layers are saved as images with transparent backgrounds, making them well-suited for detailed editing workflows.
* Training Framework: [DiffSynth-Studio](https://github.com/modelscope/DiffSynth-Studio)
* Base Model: [Qwen-Image-2.1](https://www.modelscope.cn/models/Qwen/Qwen-Image-2.1)
* Dataset: [PrismLayersPro](https://www.modelscope.cn/datasets/artplus/PrismLayersPro)
* Training Resources: 8 ZW810 PPUs
* Training Steps: 60,000 steps
Suggested prompt template: `Extract the following object: xxx`
## Showcase
| Input Image | Prompt | Output Image |
|-|-|-|
||Extract the following object: A girl with wings.||
||Extract the following object: Wings.||
||Extract the following object: A girl holding two boxes.||
||Extract the following object: A yellow hat.||
## Inference Code
Install [DiffSynth-Studio](https://github.com/modelscope/DiffSynth-Studio):
```shell
git clone https://github.com/modelscope/DiffSynth-Studio.git
cd DiffSynth-Studio
pip install -e .
```
Load the models and run inference:
```python
from diffsynth.pipelines.qwen_image_21 import QwenImage21Pipeline, ModelConfig
import torch
from PIL import Image
from modelscope import snapshot_download
vram_config = {
"offload_dtype": "disk",
"offload_device": "disk",
"onload_dtype": "disk",
"onload_device": "disk",
"preparing_dtype": torch.bfloat16,
"preparing_device": "cuda",
"computation_dtype": torch.bfloat16,
"computation_device": "cuda",
}
pipe = QwenImage21Pipeline.from_pretrained(
torch_dtype=torch.bfloat16,
device="cuda",
model_configs=[
ModelConfig(model_id="Qwen/Qwen-Image-2.1", origin_file_pattern="transformer/diffusion_pytorch_model*.safetensors", **vram_config),
ModelConfig(model_id="Qwen/Qwen-Image-2.1", origin_file_pattern="text_encoder/model*.safetensors", **vram_config),
ModelConfig(model_id="Qwen/Qwen-Image-2.1", origin_file_pattern="vae/diffusion_pytorch_model*.safetensors", **vram_config),
],
processor_config=ModelConfig(model_id="Qwen/Qwen-Image-2.1", origin_file_pattern="processor/"),
vram_limit=torch.cuda.mem_get_info("cuda")[1] / (1024 ** 3) - 0.5,
)
pipe.enable_lora_hot_loading(pipe.dit)
# Extract layers using prompt
snapshot_download("DiffSynth-Studio/Qwen-Image-2.1-LayerExtract", allow_file_pattern="assets/*", local_dir="data")
pipe.load_lora(pipe.dit, ModelConfig(model_id="DiffSynth-Studio/Qwen-Image-2.1-LayerExtract", origin_file_pattern="model.safetensors"))
prompt = "Extract the following object: A girl with wings."
image = pipe(prompt, seed=0, height=1024, width=1024,
edit_image=Image.open("data/assets/image_input_2.png"))
image.save("image_extract_girl_wings.png")
pipe.clear_lora()
```