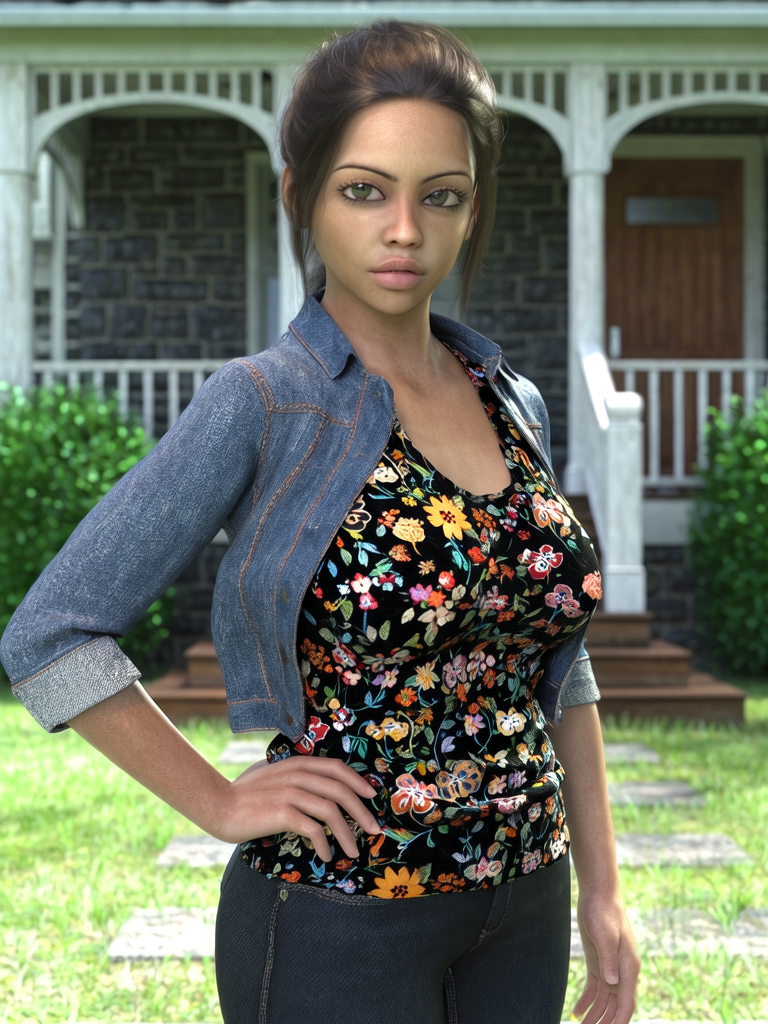
#
## Model Introduction
This model is trained using the [Civision/model training](https://modelscope.ai/civision/modelTraining) environment and computing resources provided by ModelScope.
* Model Type: LoRA
* Base Model: [openmoss/MOSS-Image-SFT](https://modelscope.ai/models/openmoss/MOSS-Image-SFT)
* Training Code: [DiffSynth-Studio](https://github.com/modelscope/DiffSynth-Studio)
* Data amount:38
* Total training steps:4000
* License: Apache-2.0
## Inference Code
Install [DiffSynth-Studio](https://github.com/modelscope/DiffSynth-Studio):
```bash
pip install diffsynth
```
Inference:
```python
from diffsynth.pipelines.moss_image import MOSSImagePipeline, ModelConfig
import torch
pipe = MOSSImagePipeline.from_pretrained(
torch_dtype=torch.bfloat16,
device="cuda",
model_configs=[
ModelConfig(model_id="openmoss/MOSS-Image-SFT", origin_file_pattern="transformer/diffusion_pytorch_model*.safetensors"),
ModelConfig(model_id="openmoss/MOSS-Image-SFT", origin_file_pattern="text_encoder/model*.safetensors"),
ModelConfig(model_id="openmoss/MOSS-Image-SFT", origin_file_pattern="vae/diffusion_pytorch_model.safetensors", computation_dtype=torch.float32),
],
tokenizer_config=ModelConfig(model_id="openmoss/MOSS-Image-SFT", origin_file_pattern="tokenizer/"),
)
pipe.load_lora(pipe.dit, ModelConfig(model_id="kick111/MOSS-Vanessa-LSS", origin_file_pattern="MOSS-Vanessa-LSS_c1-st4000.safetensors"))
prompt = "a cat"
image = pipe(prompt, height=1024, width=1024, seed=0, num_inference_steps=50, cfg_scale=3.0)
image.save("image.jpg")
```