
zImageBase - v1.0
Forgot to explain:
I've added a few things, actually a lot, to the zImage version. The most impactful negative words / tags are most likely "blurry, low-quality, low-resolution, compression artifacts etc."
The hyperbolic part is a bit tricky to explain. Some people tent to use a lot of exaggerated, melodramatic words that are either hyperbolical and attempt to "enhance" the image or just opinions and not facts. In my thought process and after some tests, that stuff has potential to kill realism and natural looking images ( Realistic and Illustrative ). How much of it was trained in zImage, dunno.
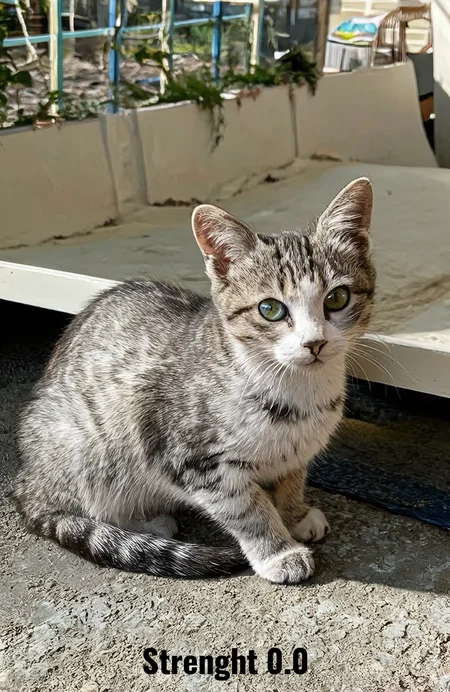
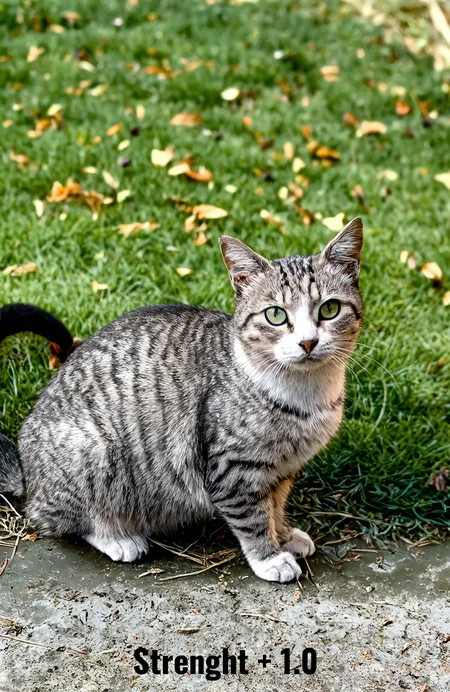
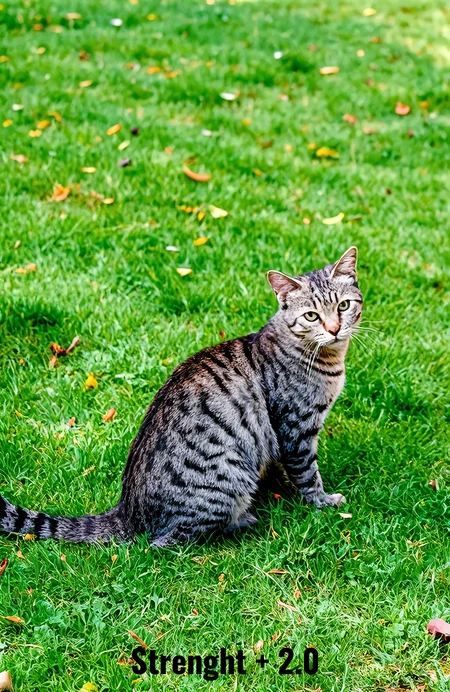
Also, the positive is neutral, no words added, so the more strength the further away from the negative without adding something positive.
Don't really wanna go to deep into that topic. See it more as my own "opinion", because in the end, i'm training all Loras for my own curiosity and not to please anyone else. People can choose on their own if they wanna join the ride.
Still testing. Slider tent to produce hallucination if trained to much or if the strength is to high. With +3 the example picture looks more like a cat, had this happen with a few other test where it really goes for realism with more illustration or digital art prompts. Have another version with less steps that is more balanced, where the negative is not as aggressive. For now - strength is a bit to much.
Will see.
Description
FAQ
Comments (9)
What is this exactly? I'm not sure.
Added a little description.
I'm not entirely sure what this is, but when I tested it on ZIT, it seemed to reduce noise. It feels like something very useful.😀
The effect of this lora is to make the character's limbs accurate, right? After I used it, there were far fewer broken limbs
it seems like embeddings, where instead of polluting your prompts with mystery terms baked into the embedding, it's an attempt at reweighting common terms in prompts to make them more/less impactful.
"so the more strength the further away from the negative without adding something positive"
Hmm, don't really know. Maybe a just lucky side effect. With all those newer models, capitations are more important than Loras, especially with zImage it seems, which takes the prompt very literally.
It would be cool to know a bit more about the Chroma version. I use Chroma Flash to speed things up, but it means I don't usually use negative prompts... will this do anything?
Wish I'd experimented with this sooner.
I'd describe this as a Negative Embeddings LoRA.. but more subtle. 1.5~2.25 was the best range for me.
My prompt had a Woman from a Character LoRA sitting in a car.
- Str 1.5: She felt more grounded in realism, smiled a bit more naturally, car windows felt more like glass, the depth of field creating a better sense of scale, and some of the weird environment compression artifacts cleared.
- Str 2.25: Same as above but stronger, with the added benefit of correcting anatomy-object transposition and ambiguity. FOV widened and matched the prompt more accurately.
Can you make Krea2 version please