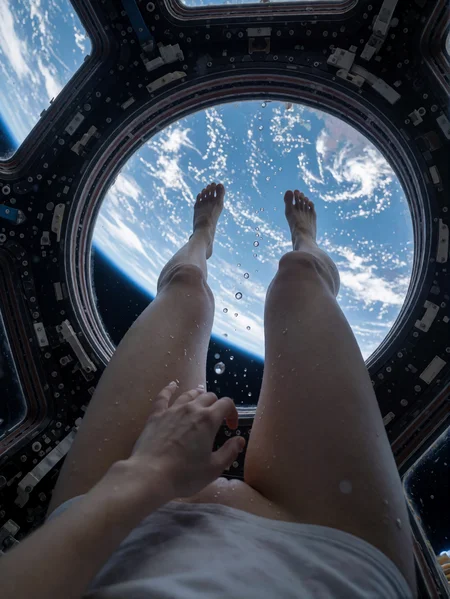


HerPOV — First-Person Female POV
-- Moss Image Base--
V2.0
Update: Reduced the data set to 69 very high quality images with significant improvements!
Prompting Guide: Start with a "first-person POV looking down the subject’s own body" then naming whats in frame (ie breasts, nipples, stomach, belly button, shaved pubic area, and how the legs are posed). Define the bottom of the image (breasts, stomach, belly button), middle of the image (feet on the ground, bent legs), and top of image (background, activity, ect).
Trained on Ostris AI Toolkit - batch size 4 - lr 0.0002
v1.0 live, trained on the same data set.
Needs some more finessing than I'd like. Play around with 0.6-1.0 lora strength.
Trained on Ostris AI Toolkit - batch size 4 - lr 0.0002 - couple hundred images
--Krea 2--
V2 - Her POV
Increased diversity of data - (10x input training data)
Significant improvement in understanding - (multi person interactions, mirrors, cum)
Suggested Strength: 0.7-1.3
(0.7 for more complex backgrounds/actions/more zoomed out)
(1.3 for more stable, close up view)
Trigger word: Her POV or POV
V1
My first LoRA for Krea-2. Trained to give you a first-person point-of-view from a woman's perspective. The camera is her eyes, looking down at her own body (thighs, lap, hands, etc.).
Trigger word: herpov
Recommended strength: 1.0 – 1.5.
Training details:
- Trained with ostris/ai-toolkit
- 3000 steps, lr 0.0001, adamw8bit
- LoRA rank 32 / alpha 32, bf16
- Multi-resolution (512 / 768 / 1024), batch size 1, ~40 sample photos
Description
FAQ
Comments (4)
Thank you, that's awesome LORA.
How long it takes to train compared to z-image?
Details
Files
k2-herpov-v1.safetensors
Mirrors
k2-herpov-v1.safetensors
k2-herpov-v1.safetensors
HerPOV - Krea2 - herpov,1.0-1.5str.safetensors
HerPOV - Krea2 - herpov,1.0-1.5str.safetensors
HerPOV - Krea2 - herpov,1.0-1.5str.safetensors
k2-herpov-v1.safetensors
HerPOV - Krea2 - herpov,1.0-1.5str.safetensors
HerPOV - Krea2 - herpov,1.0-1.5str.safetensors