


Introduction
We are excited to open-source Qwen-Image-2.1, a unified text-to-image generation and image editing model in the Qwen family. With just 7B parameters in its visual generation component (32 Single-Stream DiT layers), Qwen-Image-2.1 balances generation quality, inference efficiency, and versatility.
Four key improvements define this release:
Compact and Efficient — A lightweight architecture with mixed-granularity attention and prefix KV cache reuse delivers strong image quality at low computational cost.
Native Transparency, Unified Creation and Editing — Generate regular or transparent (RGBA) images from text, edit transparent layers, and extract subjects from photographs—all in one model.
Versatile Editing — Support up to 10 reference images, specify local edits via circles, painted annotations, or separate masks, and preserve identity for people and products.
Realistic Textures and Refined Aesthetics — Improved typography, portrait lighting, and fine details for more visually compelling results.
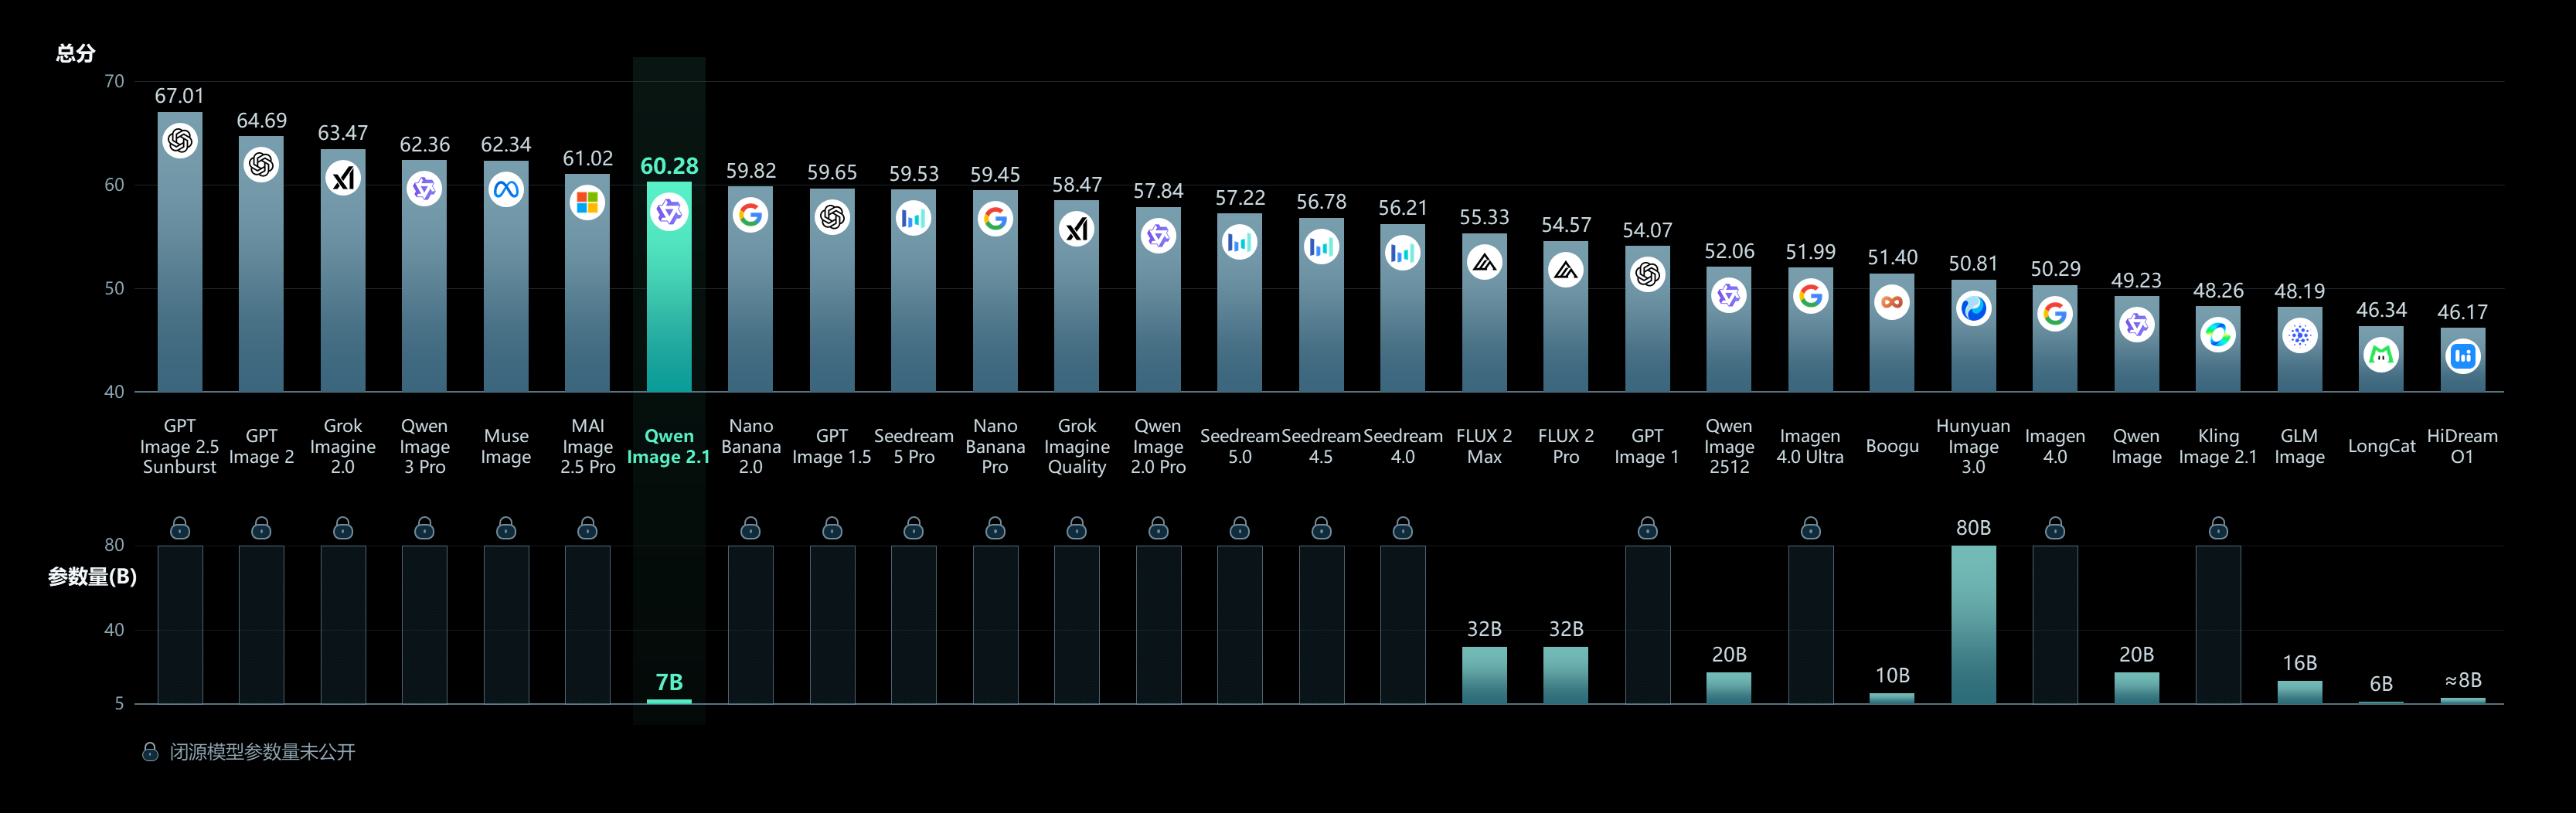
Showcase
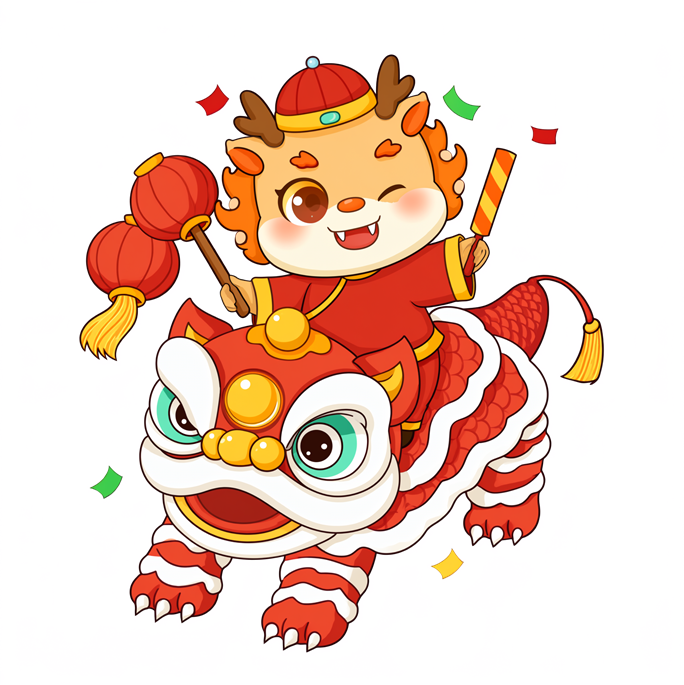
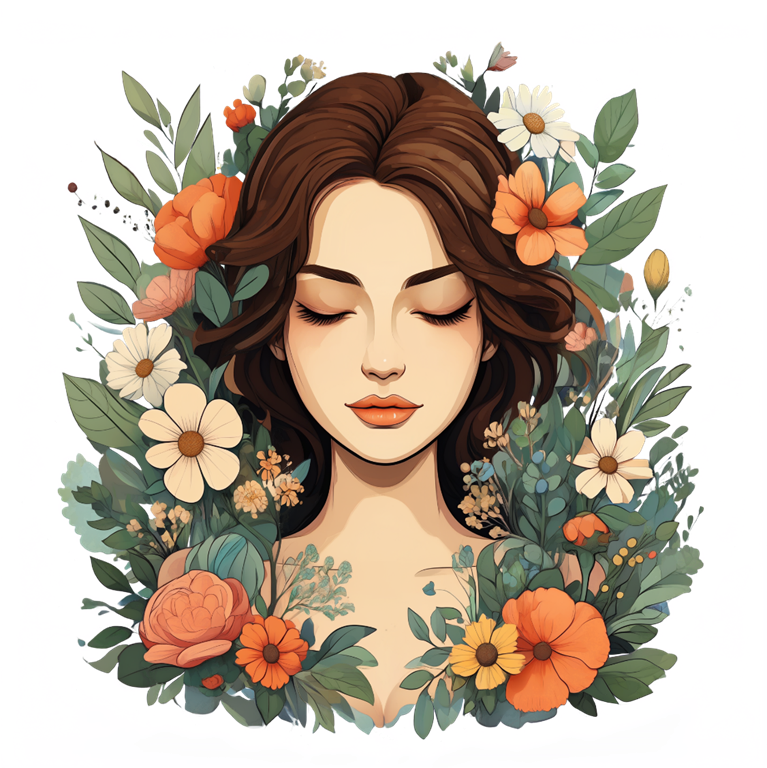
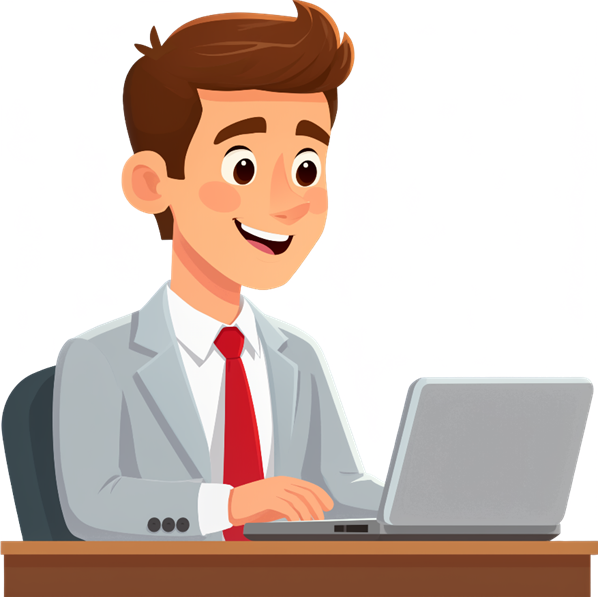
Native transparent image generation
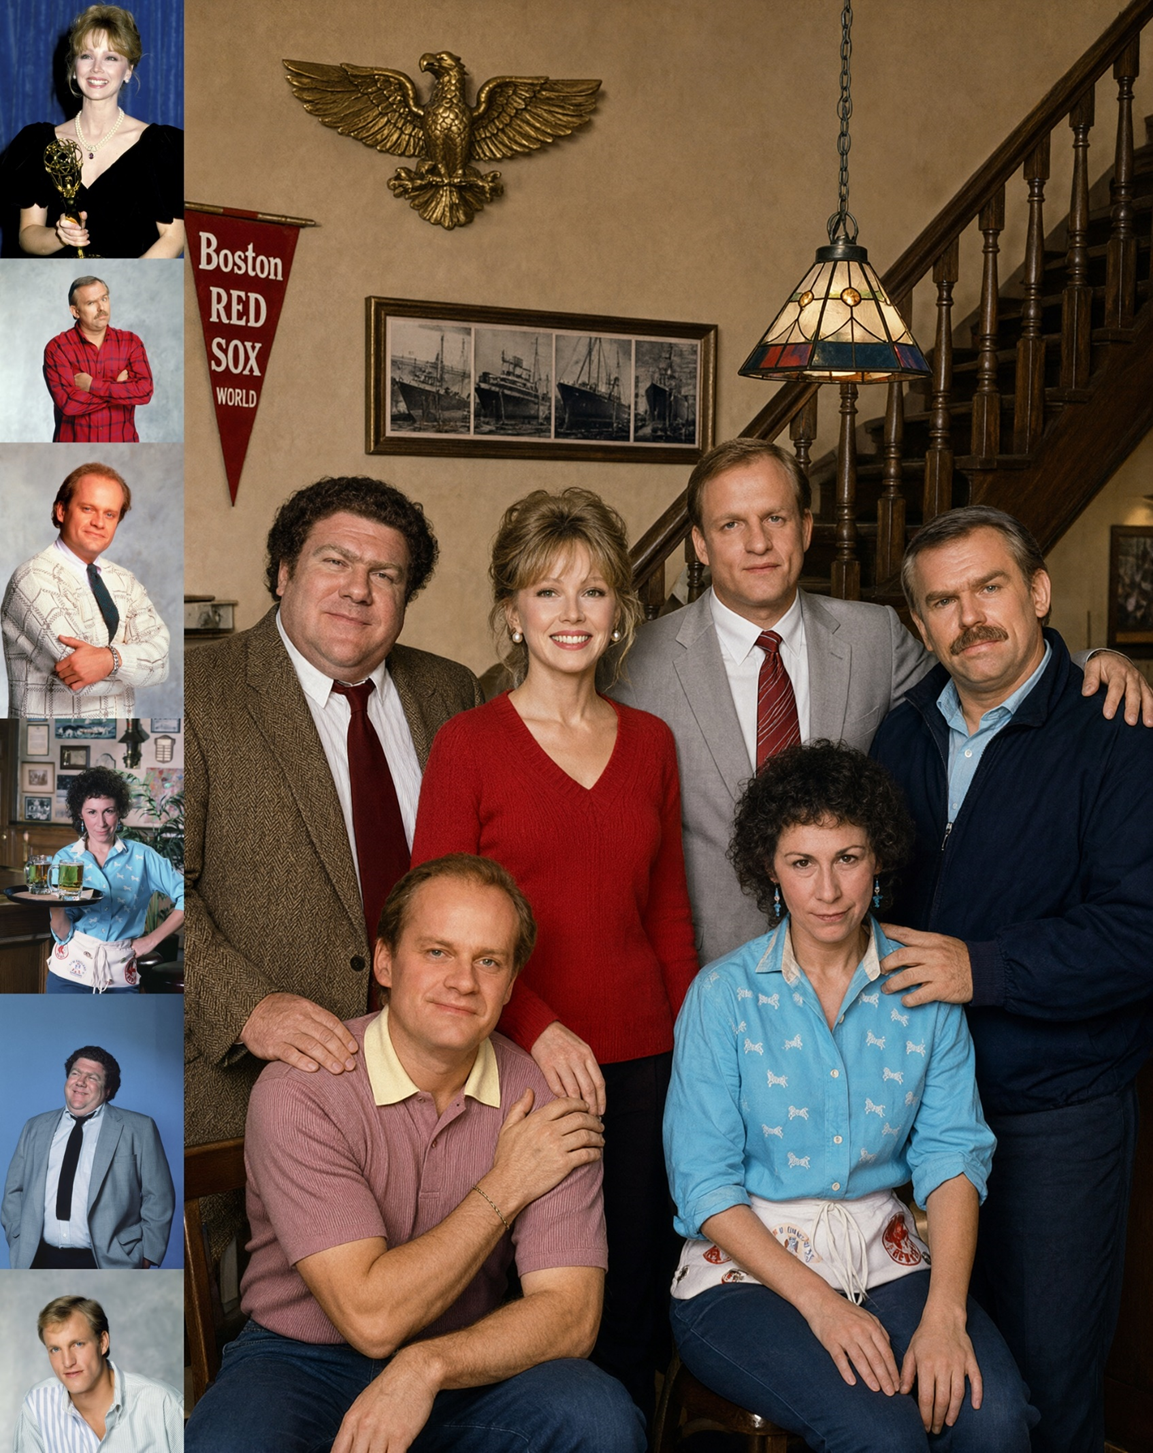
Group photograph generated from six portrait references
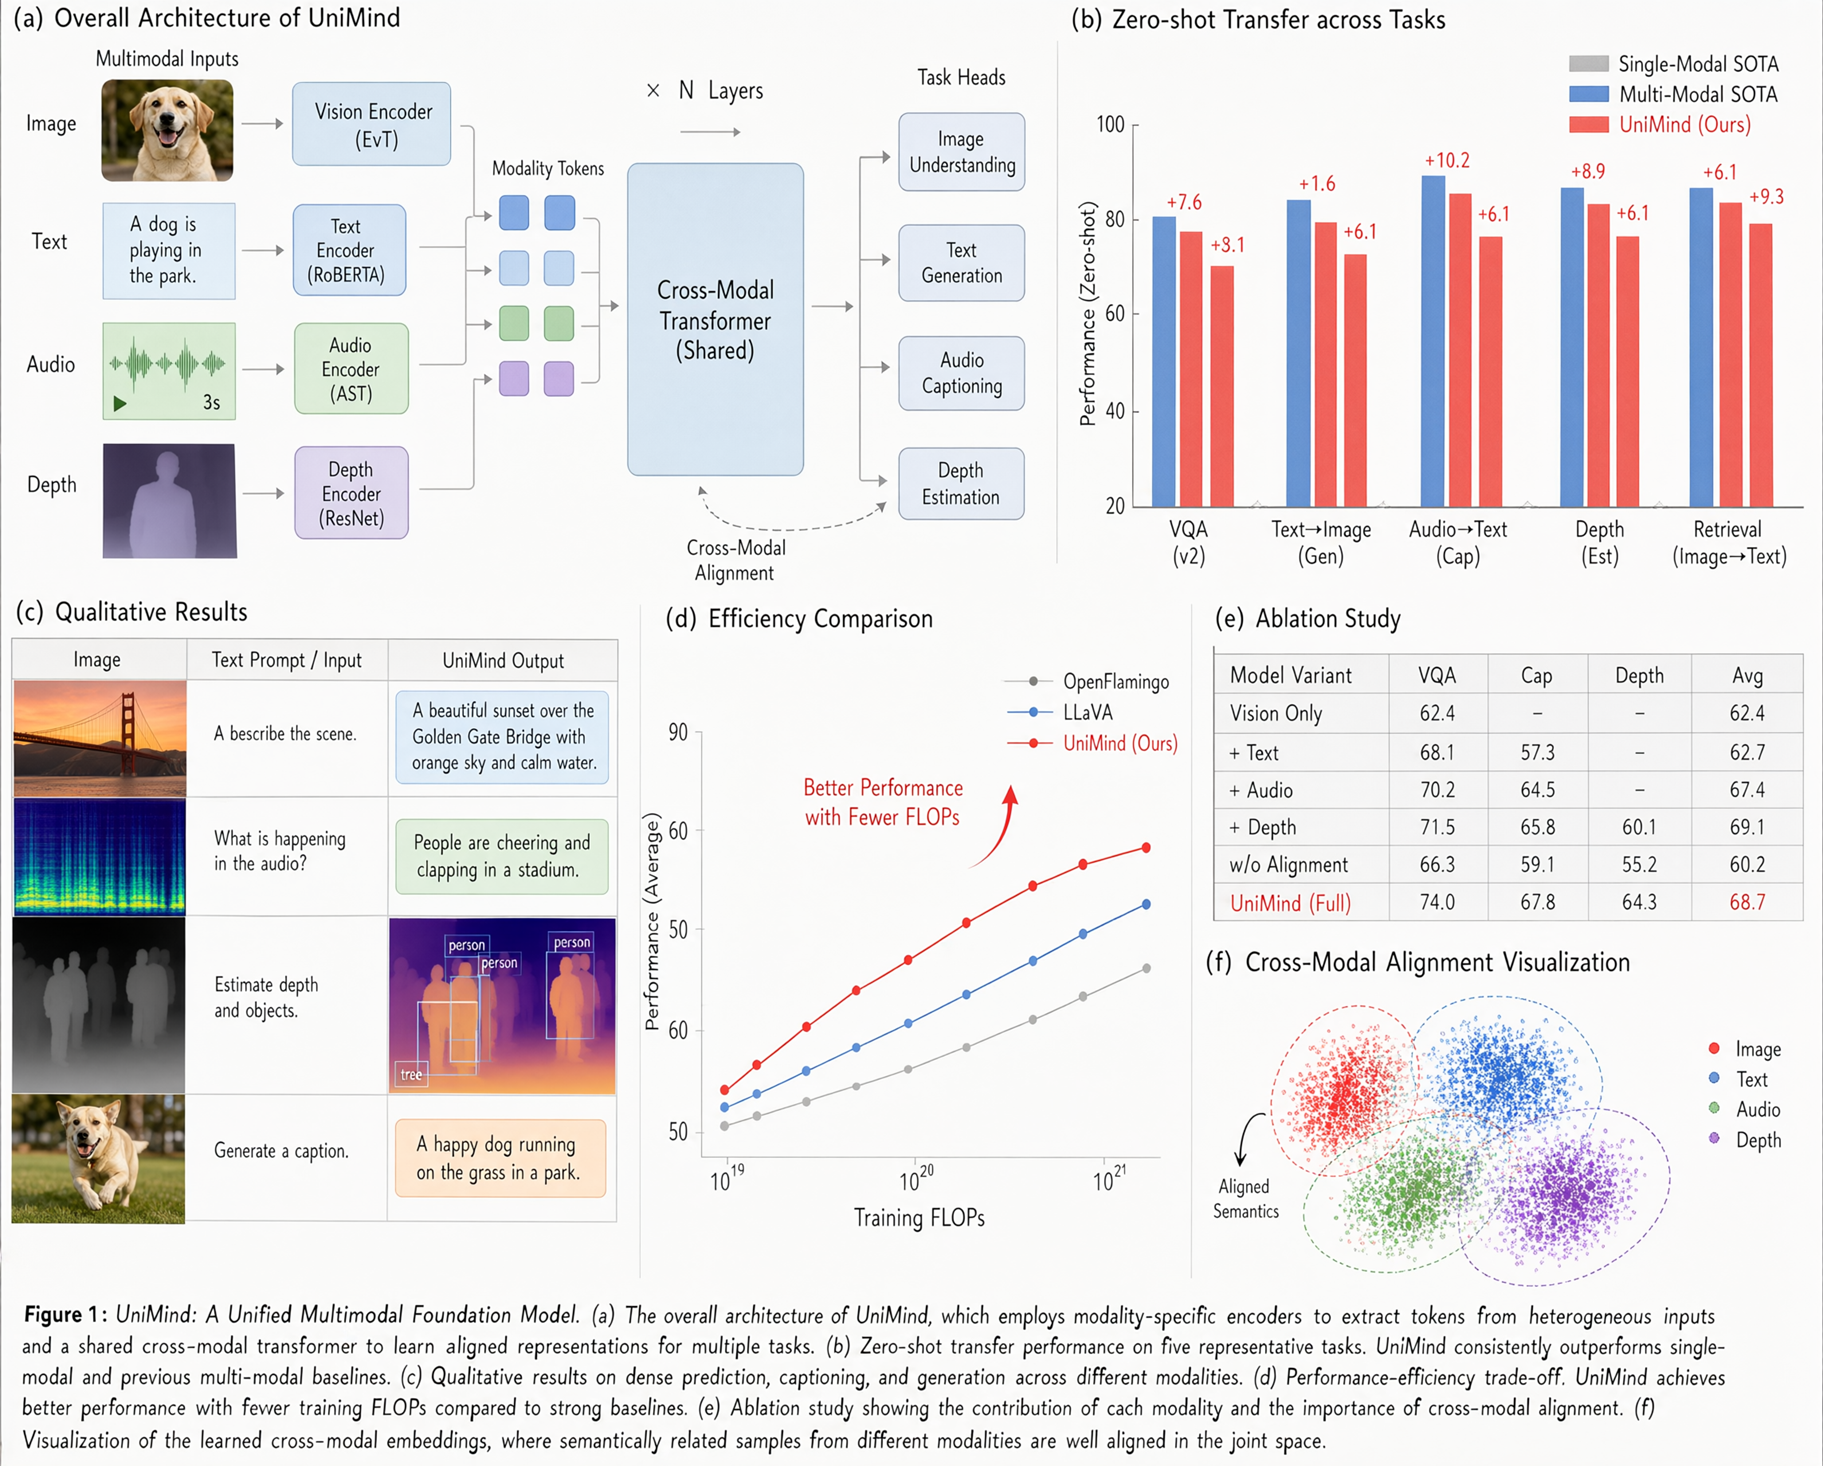
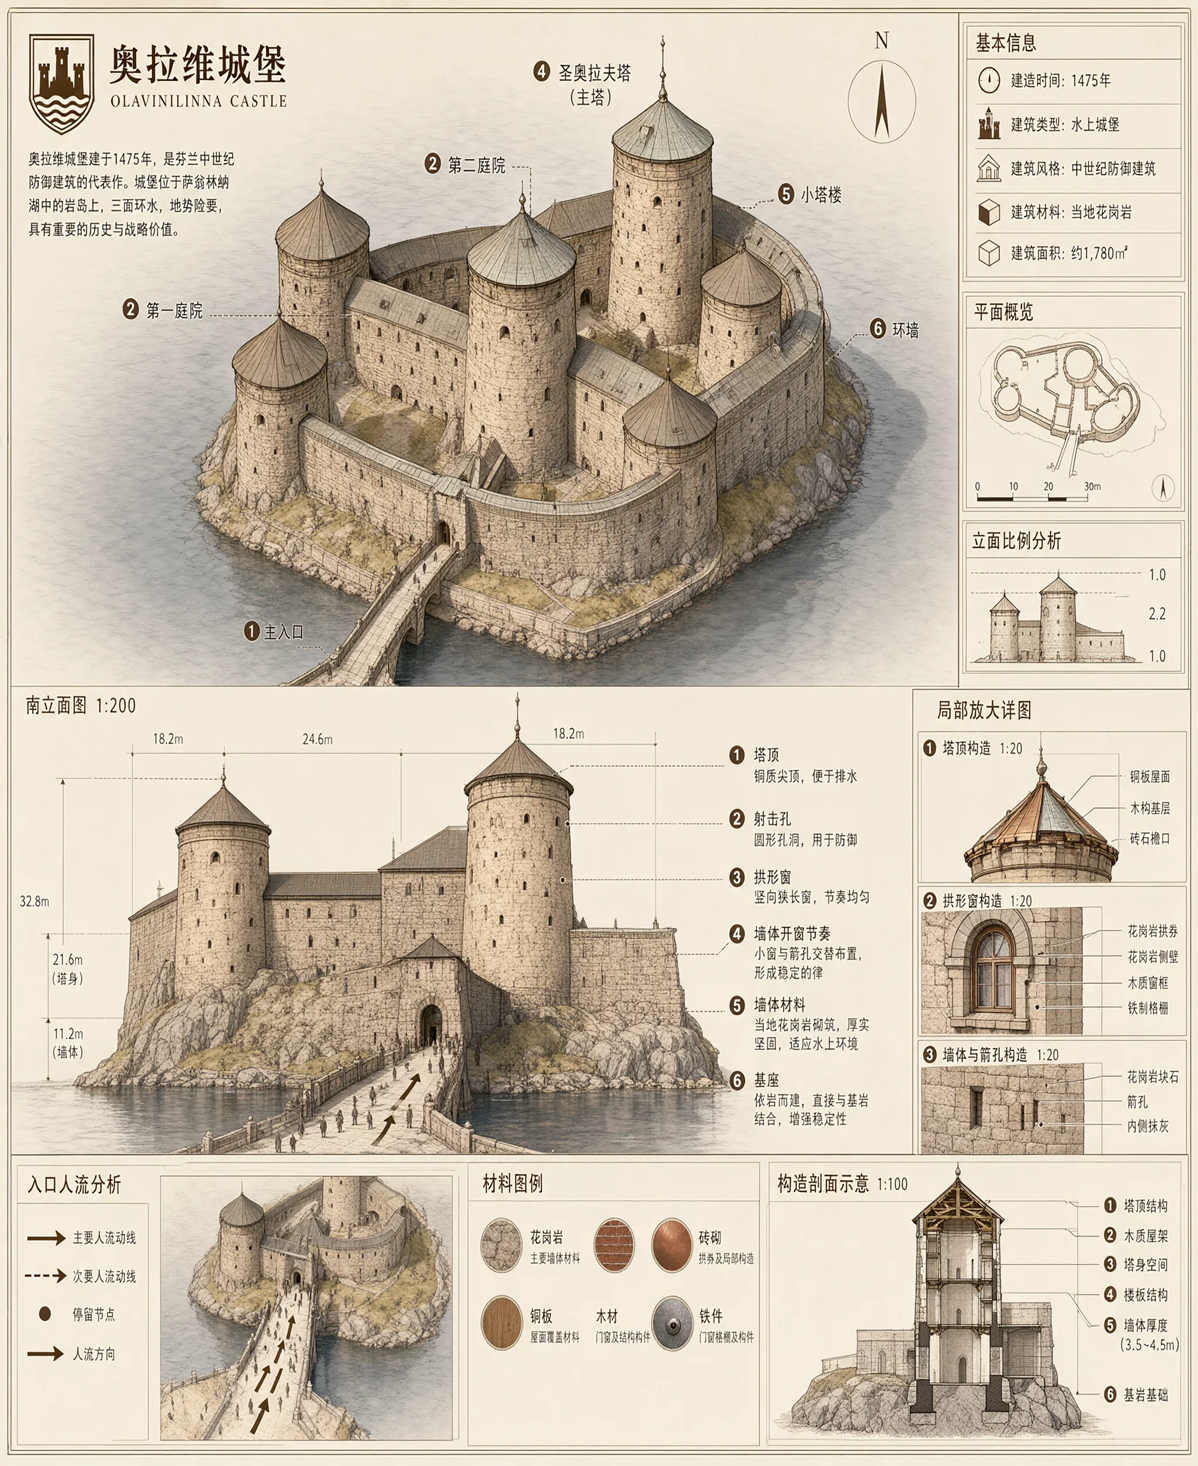
Text rendering
Description
FAQ
Comments (6)
make 4 steps loras fast as possible
Beware the model will apply a dither to all realistic images.
whats a dither
@deitychaser I thought it uses a dot pattern to cover certain colors, which can sometimes make the picture look glitchy — if I’m not wrong.
nsfw is bad, I think it cant work
Why was this archived only a few days after its release?