





RDBT [Anima]
A general finetuned model, better overall quality, better prompt adherence, less artifacts and errors.
Dataset contains ~10k images, handpicked by professional amateur artists, captioned by latest LLM. Accurate body/hands anatomy. Complete background.
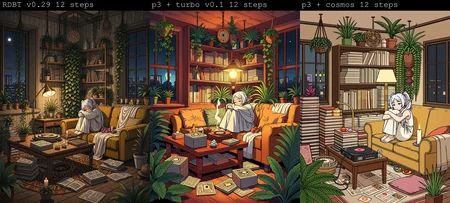
Some cover images look ridiculous; they're just for demonstration purposes for corner cases.
Update log and version info: link.
For advanced users: RDBT model is trained as LoRA natively. link.
Usage:
Settings:
Base version: has a suffix "base". Not distilled. CFG 4 and steps 24+ is recommended.
Distilled version: CFG: 1~1.5. Steps: 16+. FYI: CFG 1 = Disable CFG = run the model 2x faster. Cover images are without CFG for demonstration. "RenormCFG" node is highly recommended if CFG is enabled (CFG > 1), set "renorm_cfg" value to 1.1.
Sampler: Euler (best diversity), Euler a/er_sde etc. (better stability)
Res: 1MP
Prompt:
Always specify @style in prompt, or use a style LoRA. Otherwise, you will get random/mixed style.
Quality tags:
Omit ALL quality tags. The fine-tuning dataset has higher quality than "masterpiece". Thus quality tags don't have effects. Omitting those redundant tokens allows LLM to pay more attention on other words.
FAQ:
Why I won't bake a default style:
If a model has a "default" style (ignores prompt and is always active). We call it "overfitted". Technically, it's not a feature, it's a bug. This means the training dataset is not big enough, and the model has lost its ability to generate other styles.
The goal of RDBT model is to "perfectly" reproduce styles. As some of you know, I use this model to aid in drawing. I need unique textures and details, instead of uniformed 2.5D AI slop style.
This model has excellent compatibility. You can stack any type of Lora on it. After all, it's you who decide what style you want, not me.
RDBT can't remove nor resist overwhelming Al slop effects
Too long, see: link.
My homemade distillation vs Anima official turbo model:
Official turbo: 8 steps. High stability, low entropy. Adds a strong 2D anime filter that will overwrite style and cause style shifting.
My homemade distillation: 16 steps. High diversity, low stability. Minimal style shifting.
Sharing merges using this model is not allowed.
This mode is a free and it will always be free. This "restriction" won't affect anyone. It's only aimed at those who steal others' models to sell.
Known model thieves: NukeA.I (selling this model behind paywall on tensorart).
Because he is such a jerk I wrote a story about it. Also contains a guide for trainers about "how to bake special trigger word into your model".
Description
FAQ
Comments (21)
Without picking a specific style, the generated characters lean into a semi-realistic AI look (tested 10+ times). It works perfectly for anime styles once I add the right style tags. Overall it’s pretty good, gonna go test out more style tags next.
Yes, there is no default style. Without style conditions distilled model will give you the "ultimate AI style" that averaged every style. Which looks really bad.
Bossman producing banger after banger
0.29 produces some great results when you're asking for something generalized and well understood but I feel like prompt adherence went out the window for fringe content. Anima as a whole is really good at mashing concepts together using natural language, but throw in some simple contradictions ("A solo illustration of a girl with a penis") and it struggles to understand.
Try and make sure that you specify the style or artist at the beginning of the prompt to lock in that style. Otherwise it can be a little bit wild with all Checkpoints especially the base one. pretty much all of them unless it's specifically stylised towards a specific style.
I know you are not really supposed to use the turbo lora with this checkpoint since it's already turbo/distilled to begin with... buuuut I did anyway and the results are honestly very interesting. A lot less detail but VERY strong 2D anime styles are possible with very stable composition. I kind of love it. Posted some pics.
I've tried it with the Cosmos Predict 2.5 DMD2 LoRA too and it works well.
Like the other person, I tried v0.29 RDBT Checkpoint, Cosmos Predict, and Anima Turbo LoRA all together with 4 steps. Pretty interesting stuff!
What you say interesting? Do you mean it was good and stable. As I guess using multiple DMD2 LORAs that all distills both steps and CFG might over distil the model.
V0.29 exceeded all limits in flash-banging with 3D looks/shading
Further we are from V0.24 the worse 3D it gets :(
"Style is required! This model does not provide a default style. You should always prompt specific style. Or use a style LoRA. If you don't give the model style conditions, the model will give you the "ultimate AI style" that averaged every style because of dmd2. This is a "feature", not a bug. I don't like bake a strong style into the model, I prefer having choices."
You need to add some "@artist" tags.
v0.29 Has to be THE best finetuned ver of Anima P3!
You've done such a good job with this. Honestly.
It's even 12 step!
v0.29 has too much 3d bias that it affects styles for "digital anime illustration" and "anime screenshot" which was already perfect on v0.27. I know we should specify artist style but why change those mentioned styles? Comparisons here: https://civitai.red/images/129069519
I didn't change those styles. "digital anime illustration" was not a specific style (that's why I called it "rough"). It was mapped to almost everything, from unfinished lineart to finished art with complicated lighting. Because it was trained so it can regulate the style if needed, but not required.
https://civitai.red/posts/28267425
assume this post won't disappear,
Any suggestion when animal ears and tails, or the animals itself come out from nowhere...? The negative prompts won't work. Even when I input all the related words about animals in the prompts.
This is a good model, but unfortunately, it has almost completely lost its ability to generate watercolor-style images. I wonder if there is a bias in the dataset used for distillation.
Furthermore, the effectiveness of artist tags characterized by pale colors has declined significantly.
New versions after v0.25 significantly improved image detail, a LOT.
This caused the model to consistently generate realistic backgrounds unless a minimalist background was specified in the prompt. and simply adding "anime coloring" "screenshot" won't work.
But, after testing, model can generate very complex backgrounds. And it actually has better prompt adherence.
If you think image is way too detailed, but don't want to change prompt, you can mix rdbt with anima turbo v0.1 0.5:0.5.
I still yet to find a model that i'm able to use on anything than yours, other fitune always change character face and such to a degree, it's super fun to make anima lora and use your checkpoint x) you'll probably be floaded each time i publish a lora by exemple image xD