


(22/10/2026): v3.0 should be the final version for Anima. Next: MOSS Image (aka. The greatest anime model that has ever been released.). Here.
RDBT [Anima]
A general finetuned model, from a personal all-in-one dataset, mainly for digital art and drawings, focusing on lighting and textures, from wallpaper level digital art to 5-min sketch.
Dataset contains ~10k images, handpicked by professional amateur artists. The criteria for evaluation are not visual appeal, but the drawing technique and the level of completion. Captioned by LLM.
Some cover images look ridiculous; they're just for demonstration purposes for corner cases.
Update log and version info: link.
Useful links:
RDBT | Digital Art: My merged 16-step ckpt optimized for digital anime art. 4x faster. Easy to prompt.
RDBT | Original LoRA: LoRA files for advanced users.
16-step Acc LoRA: Style friendly, less AI slop, compared to the official Turbo.
RDBT | 160KE6 Furry: Based on 160kE6Anima by @garaggge. 160kE6Anima "was trained on around 160k images from e621". It has extended knowledge and 3k+ style tags. Check its model page above for more info (list of styles, etc.).
Settings:
Base version: CFG 4 and steps 24+. Euler.
Distilled version(8s, 16s, discontinued): CFG: 1. Steps: 8 or 16. Euler.
Prompt:
Always specify @style in prompt, or use a style LoRA. This model does NOT provide overfitted default style (ignore prompt and is always active). You need to specify style in prompt, or use a style LoRA. This is a feature, not a bug. The dataset is big enough and model is not overfitted. Otherwise, you will get random/mixed style.
Quality tags:
You don't need quality tags. The dataset has higher quality than "masterpiece". Thus quality tags don't have effects. Omitting those redundant tokens allows LLM to pay more attention on other words.
Sharing merges using this model is not allowed.
This mode is a free and it will always be free. This "restriction" won't affect anyone. It's only aimed at those who steal others' models to sell.
Known model thieves: NukeA.I (selling this model behind paywall on tensorart).
Because he is such a jerk I wrote a story about it. Also contains a guide for trainers about "how to bake special trigger word into your model".
Description
FAQ
Comments (14)
It is a slightly different experience, but it is appreciably better. The work you have done on this model series is remarkable and significant.
The newest checkpoint is really, really receptive to any visual style prompting. My signature "The art style has realistic proportion and mature face shape" which works almost like placeboo for most other model, has significant and noticeable changes visually to the part I prompt. Add "flat color", and it makes the color flat. Add "slender body type" and holy, it actually makes the character body slender! Impressive visual style prompt adherence.
Besides individual visual element style, it also has good adherence to a 'x style' (not artist tag), Hella surprised that "Persona 5 style" actually gives you a very good recreation of it. Not as accurate as a specifically trained style Lora but it has own flair that makes it unique. This makes me want to explore what "other style" this model could make.
To close this off, this model is really receptive and reactive to style lora. At 1 strength it almost certain your style lora will be overcooked by this model. 0.8-0.9 is the best starting point for style lora that usually has 1 as a default.
Do you have tips on getting Boa Hancock's 'snake earrings' correctly? I'm struggling with it, and I really don't want to go and create a whole character LoRA just for that one specific object. 🥺
@monicalucci My quick test on the 0.43 RDBT shows that you just need to put "earrings" either as a tag or as part of natural language description of her. In this regard, try to be as minimal as possible, avoid using "snake earring" both as tag or natural language because a checkpoint isn't trained to differentiate it. Earrings is enough and the checkpoint should've render the earring shape that she's associated with.
The shape isn't quite accurate, but without lora that is to be expected. Further, the less focus on her head (waist-up vs cowboy shot), the more likely for her earrings shape to be less accurate especially if there's another character beside her.
cool but ignores solo prompt and adds unwanted characters to it previous version was better
You could try to increase CFG for more prompt adherence or use more natural language. Maybe instead of something like 'solo, 1girl, standing, park' you could just say 'a girl standing in a park'. Anima is great at following natural language and I utilize it all the time
@MeisterGoon yeah i know i used earlier versions and worked ealier better then the new one it has the same stuff as mios anima model that one does the same with multi chars :/
Thanks for the feedback. I'm guessing you are taking about v0.39 and v0.39.b with CFG 1.
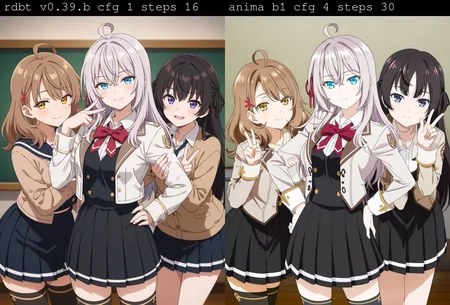
v0.39.b does has some issues if you use cfg 1. Too creative. Sometimes it can't fully denoise the image and left artifacts.
CFG 1.5 produces nice results for me. I realize it's twice as slow as using 1 but you can still get away with 12-16 steps in most cases so it's not too bad. Alternatively using the anima turbo v0.2 lora at a low weight like 0.3 and using CFG 1 can work to reduce unwanted elements without sacrificing speed but the turbo lora is pretty aggressive when it comes to composition so you might lose some of the seed variety which imo is the biggest strength of rdbt v.0.39b
@reakaakasky i use always higher cfg on this anima models here because neo forge deactivates negative if i use cfg 1 so i use round about 2-4 i switch sometimes around to see the result of the image and if it works better or not
@hknk speed is fine but unwanted multi chars is that what i mostly dont want
Feedback: v0.37.b compared to v0.37.0, is more versatile and adept at associative thinking. Simple prompts generate more natural and detailed images. Style Lora compatibility is also better, especially for Lora images with complex details. However, it is indeed less stable (I know this is a trade-off). There is a higher probability of artifacts and limb errors.
To be honest, I prefer v0.37.b. It feels less sloppy. You can fix errors by changing seeds or inpainting, but you can't get rid of the sloppiness easily.
If you have time please can you make a checkpoint version of your great ym1 v0.41 Lora. Thank you.
LoRA and ckpt are identical.
Details
Available On (1 platform)
Same model published on other platforms. May have additional downloads or version variants.